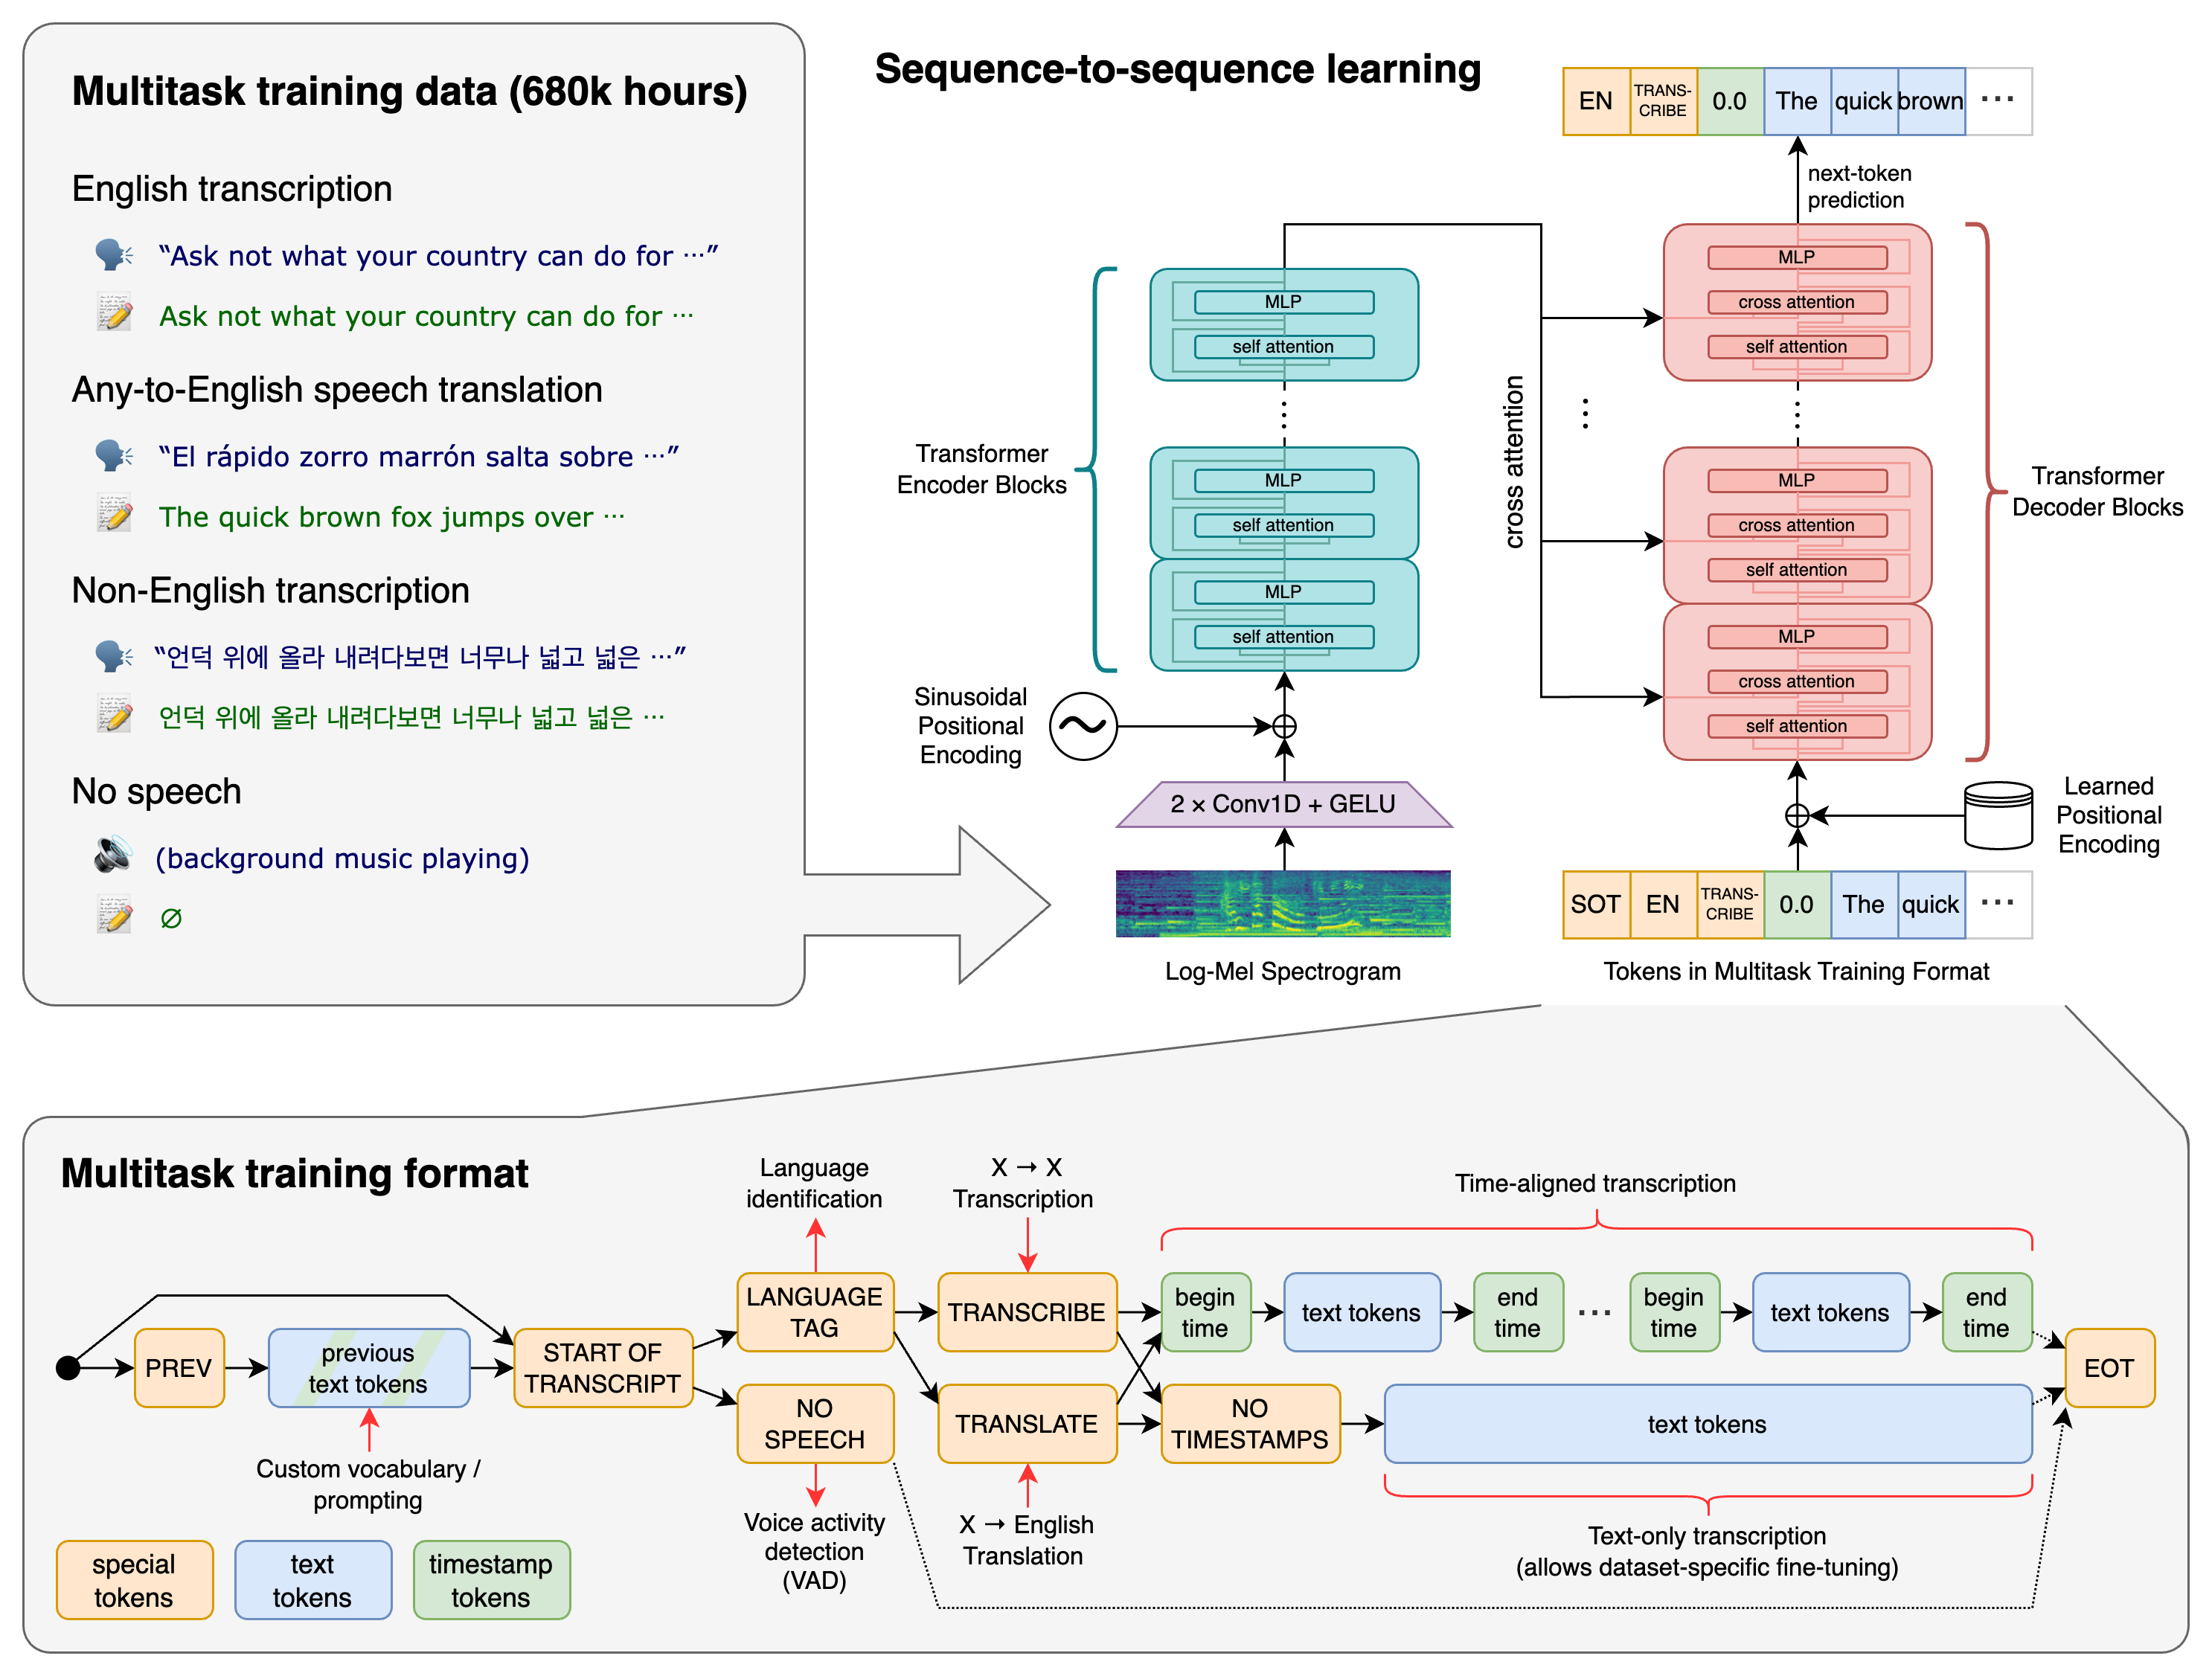
OpenWhispr is a desktop dictation app for macOS, Windows, and Linux, with a separate mobile app. You press a hotkey, speak, and the transcribed text appears at your cursor in any app. Transcription runs either fully offline with local speech-to-text models (Whisper, NVIDIA Parakeet, Orukeet, and Cohere Transcribe), so audio stays on the device, or through cloud providers with your own API keys.
Beyond dictation, a voice assistant hotkey sends spoken commands to an AI model and edits highlighted text in place, and a translation hotkey dictates in one language and pastes in another. The assistant works with GPT-5, Claude, Gemini, Groq, Tinfoil, OpenRouter, or local models through llama.cpp.
OpenWhispr also records meetings: it detects Zoom, Teams, and FaceTime calls, labels speakers on-device with voice fingerprints, and links to Google, Microsoft, or Apple calendars. Transcripts land in notes with folders, semantic search, sync, and sharing through team spaces. A public API and an MCP server expose notes and transcriptions to other tools, and organization controls cover SSO, SCIM, and centrally managed Amazon Bedrock or Azure OpenAI access.
The app is built with Electron, React, and TypeScript, and runs Whisper locally through whisper.cpp with GPU acceleration on Metal, CUDA, and Vulkan.
Features
- Voice dictation: a global hotkey dictates into any app and pastes the text automatically
- Dictation translation: a dedicated hotkey dictates in one language and pastes the text in another
- Voice assistant: spoken commands go straight to GPT-5, Claude, Gemini, Groq, Tinfoil, OpenRouter, or a local model, with optional screenshot context
- Local or cloud models: transcription, AI reasoning, speaker diarization, and semantic search each run locally or through a cloud provider
- Meeting transcription: detects Zoom, Teams, and FaceTime calls, with live speaker diarization and calendar integration
- Local speaker diarization: on-device speaker labels with voice fingerprint recognition across meetings
- Notes: folders, semantic search, cloud sync, and AI actions on transcripts
- Team spaces: shares notes by link, domain, or invitation, with roles and server-enforced membership
- Audio import: transcribes dragged-in files, batch uploads, or a YouTube or audio URL, with optional speaker detection
- Custom dictionary: learns names and jargon from your corrections
- API and MCP server: manages notes and transcriptions programmatically or from an AI assistant
- Organization controls: policy enforcement, SSO, SCIM, and centrally managed Amazon Bedrock or Azure OpenAI access