 OpenAI
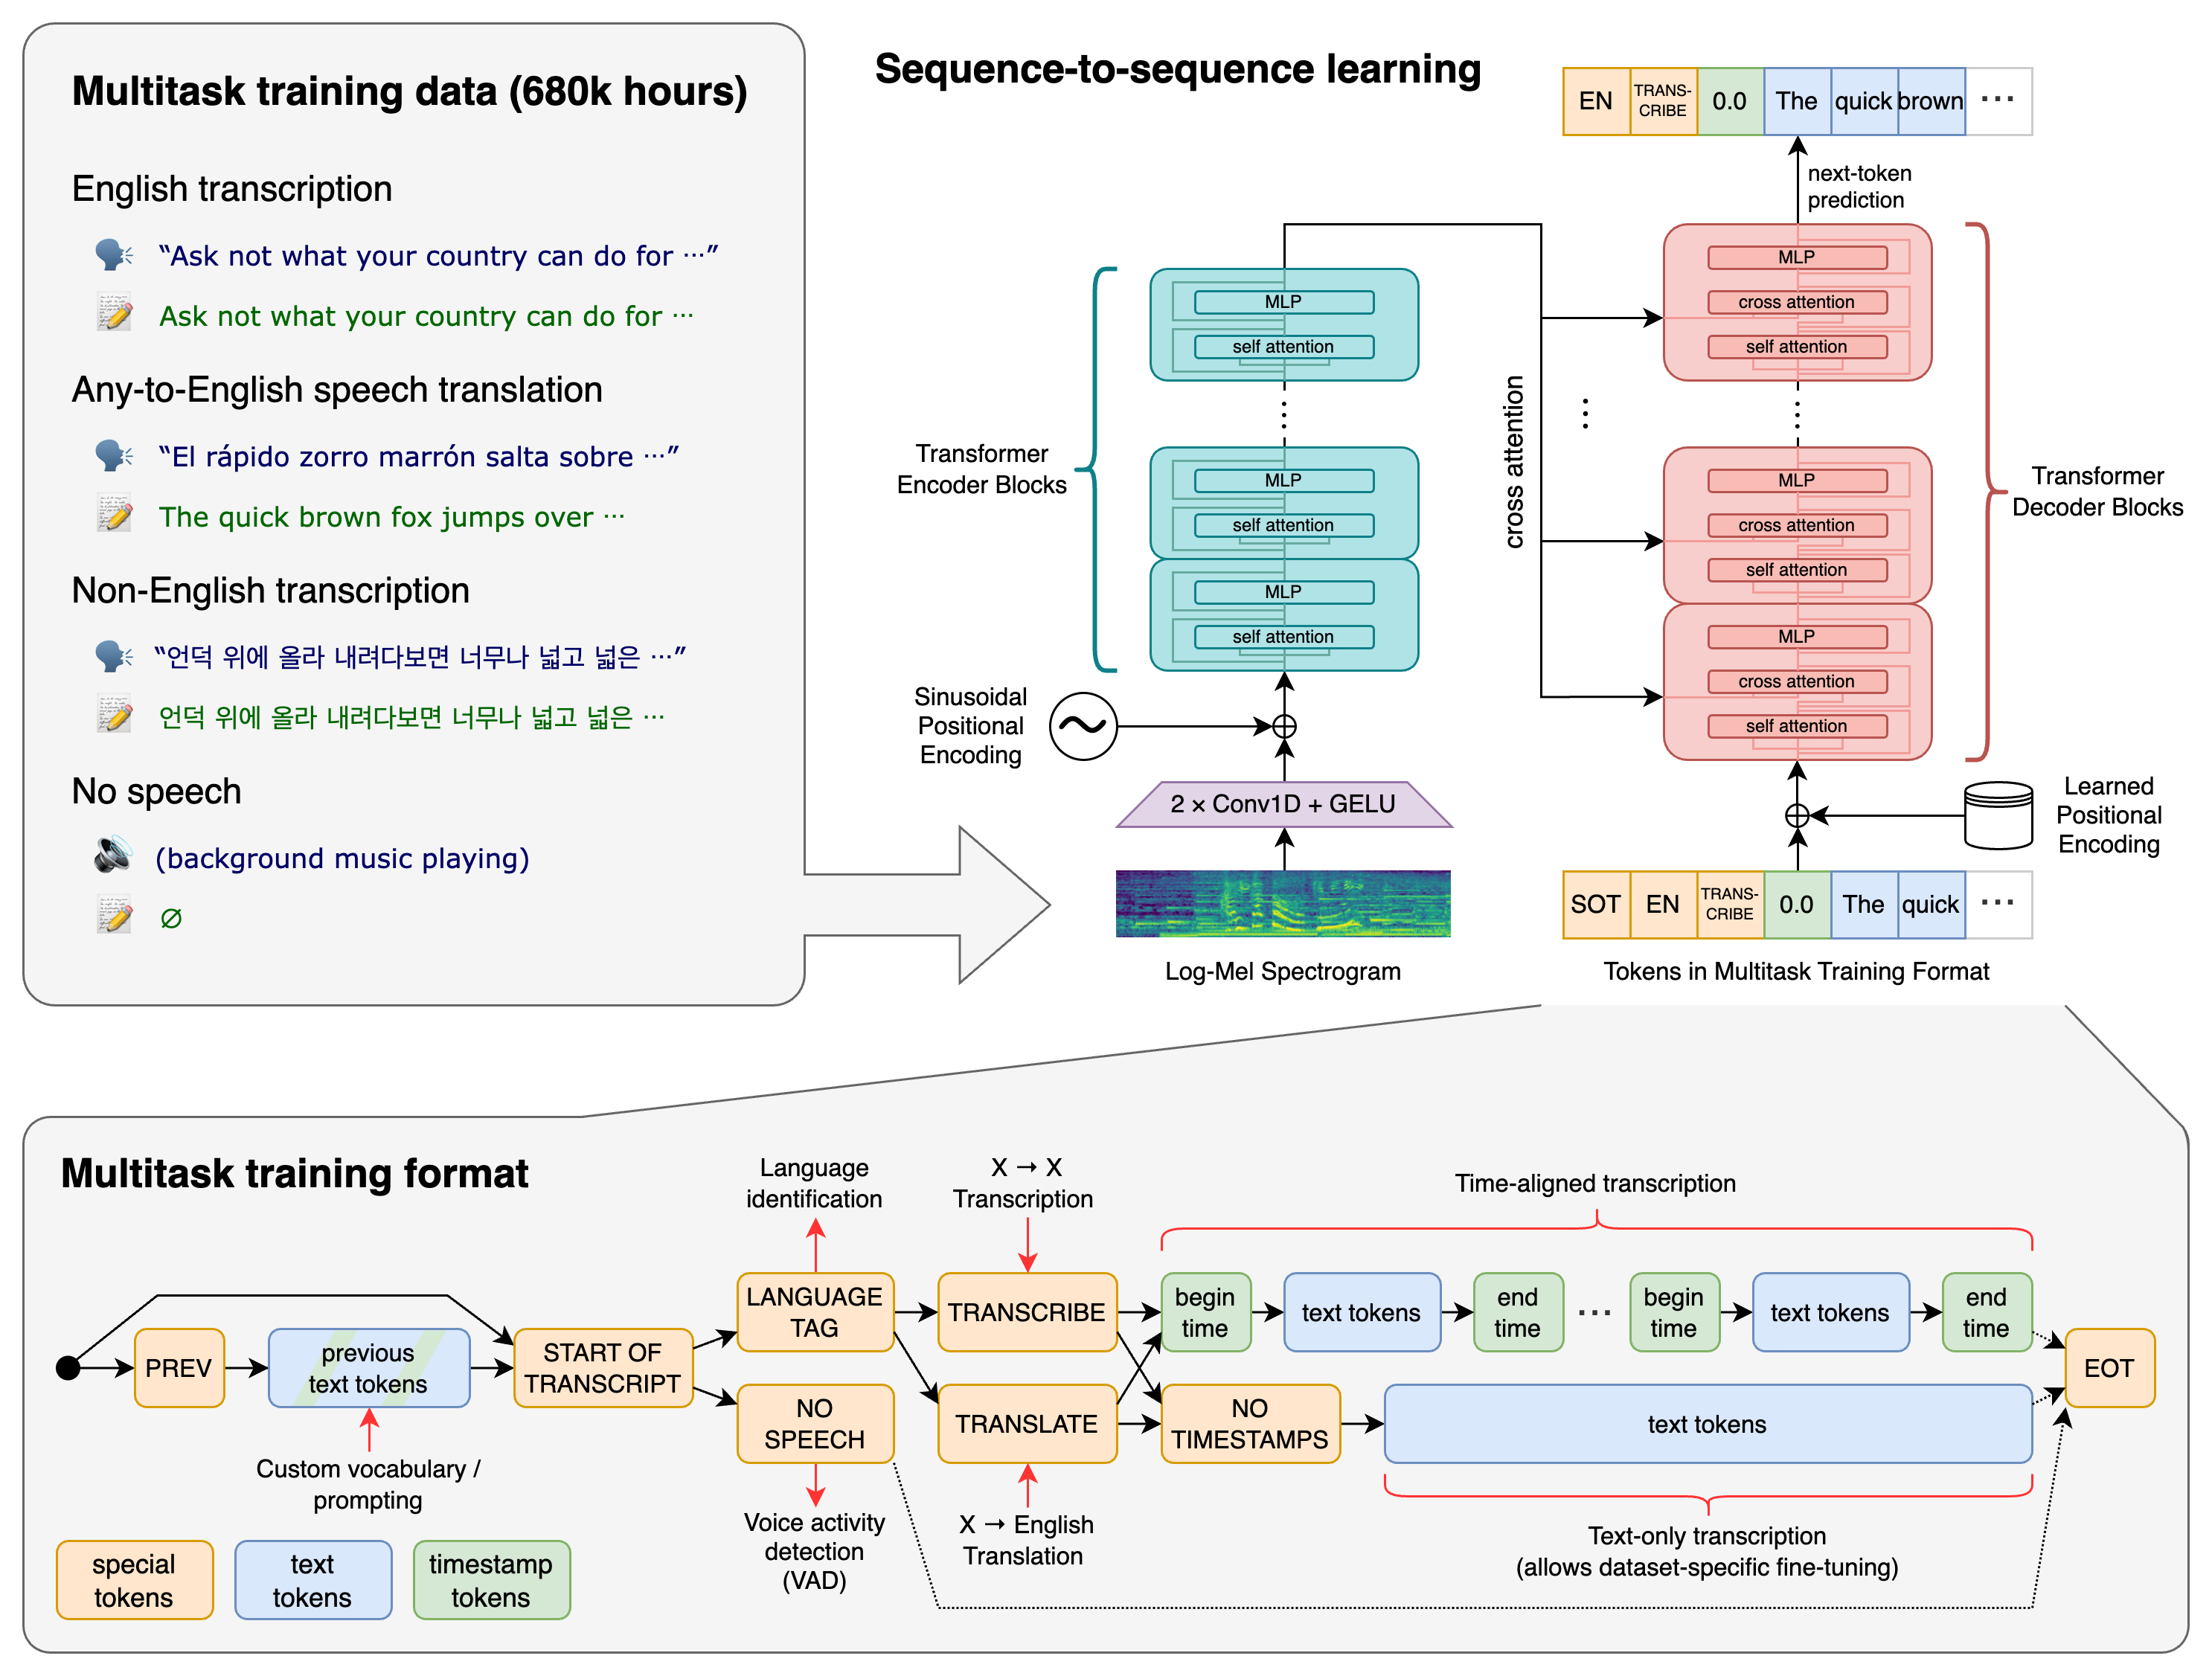
Whisper is a general-purpose speech recognition model trained on a large dataset of diverse audio. A single Transformer sequence-to-sequence model handles multilingual speech recognition, speech translation into English, spoken language identification, and voice activity detection. These tasks are represented jointly as a sequence of tokens predicted by the decoder, with special tokens acting as task specifiers, so one model replaces several stages of a conventional speech-processing pipeline.
The package provides a command-line tool and a Python API. The transcribe() method processes audio with a sliding 30-second window and autoregressive decoding on each window; lower-level functions expose language detection and decoding directly. Six model sizes trade speed for accuracy, four of them with English-only variants. The turbo model is an optimized large-v3 for transcription only; translation requires one of the multilingual models. The codebase targets Python 3.8–3.11 with PyTorch and depends on ffmpeg and tiktoken.
| Size | Parameters | English-only | Multilingual | Required VRAM | Relative speed |
|---|---|---|---|---|---|
| tiny | 39 M | tiny.en | tiny | ~1 GB | ~10x |
| base | 74 M | base.en | base | ~1 GB | ~7x |
| small | 244 M | small.en | small | ~2 GB | ~4x |
| medium | 769 M | medium.en | medium | ~5 GB | ~2x |
| large | 1550 M | N/A | large | ~10 GB | 1x |
| turbo | 809 M | N/A | turbo | ~6 GB | ~8x |
Features
- Multilingual transcription: recognizes speech across many languages, with the language auto-detected or set via --language
- Speech translation: --task translate renders non-English speech as English text with the multilingual models
- Language identification: detect_language() returns per-language probabilities for an audio segment
- Model sizes: tiny through large plus turbo, with English-only variants for the four smaller sizes
- Command-line usage: whisper audio.wav --model turbo transcribes one or more files
- Python API: load_model, transcribe, load_audio, pad_or_trim, log_mel_spectrogram, and decode
- Performance breakdown: word and character error rates per language for large-v2 and large-v3 on Common Voice 15 and Fleurs, with further metrics in the paper appendices